The Hard Part of AI in Education Isn’t the Model, it’s Everything Around it
"The metric we care about most, the holy grail, is completion. If we are able to improve completion, everything else follows."
Generative AI has made one part of building education technology remarkably easy,i.e., getting a model to answer any question. A university can now connect an application to OpenAI or Google’s models, upload course material, build a chatbot and have something that looks like an AI tutor.
But building an AI demo and building something a university can actually deploy are two very different things. How do you make sure the answer follows the curriculum rather than everything the model knows? How do you integrate the technology into an existing learning management system? What data should the AI have access to? And perhaps most importantly, how do you convince faculty that the technology is helping them rather than replacing them?
These are some of the problems Emeritus is attempting to solve with its new AI Labs division and its new offering–the LYCM suite. Emeritus believes the value of education AI will increasingly sit in the infrastructure around the model– curriculum grounding, evaluation systems, data boundaries, LMS integration, privacy controls and the ability to adapt the technology to how an institution actually teaches.
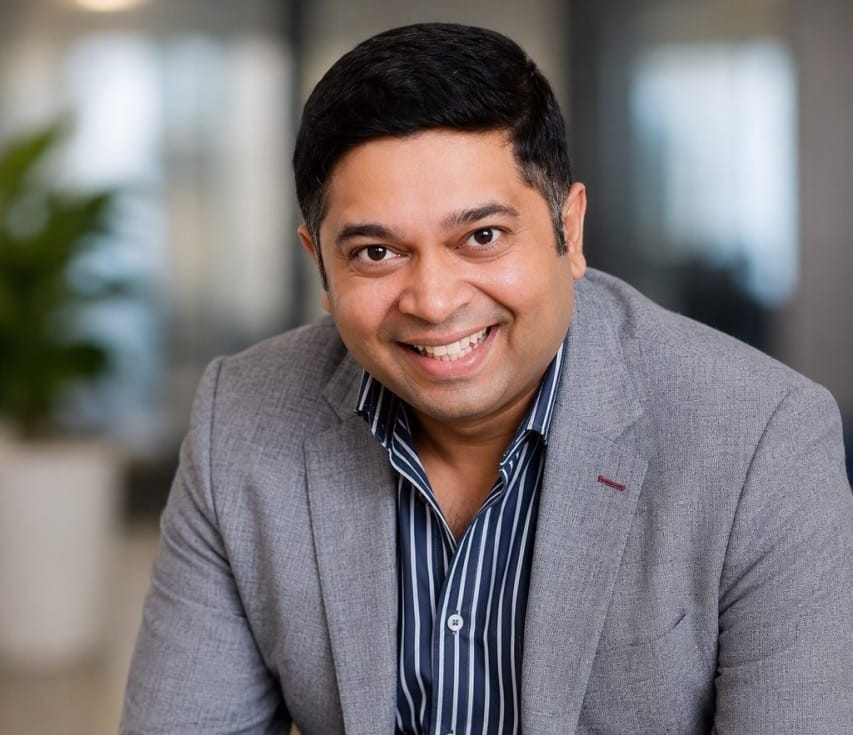
Bhushan Heda, CTO/COO and now President, AI Labs at Emeritus, believes today's relatively static model of education—fixed courses, fixed assignments and broadly similar learning paths—could eventually move towards skills-based, personalised and adaptive education.
That is a much harder problem than building a chatbot. It could require universities to rethink how courses are constructed, how students are assessed and even how accreditation works.
In a conversation with The Left Shift, Heda discussed why Emeritus believes universities will buy rather than build AI tools, what happens when an AI tutor gets something wrong, why LMS integration may be more important than the underlying model, how the company handles student privacy, and why faculty—not technology—could ultimately determine how quickly AI changes education.
Edited Excerpts
So who exactly are the customers for LYCM? Is it the universities that Emeritus already partners with, or are you trying to sell this to completely new institutions?
Heda: It's B2I—business to institutions. Over the last year, our existing partners have onboarded the products as part of the programmes we were already running. That was our journey through last year.
Schools have a very high bar when it comes to privacy and quality. For many of them, reputation is everything. So we went through a significant amount of rigour and diligence to work with them.
During our collaboration, we had more than 50,000 learners using our tools. That gave us a baseline for understanding how much impact we were actually having.
The metric we care about most, the holy grail, is completion. If we are able to improve completion, everything else follows. So far, we've seen meaningful improvements in completion, and we've also seen very strong engagement with the tools. Having gone through this phase with our existing partners and seen the impact, we are now expanding to other schools.
 Pritam Bordoloi
What are the biggest problems you're actually trying to solve?
Heda: There are three broad areas– operational efficiency, learner retention and learning integrity—making sure that everything we do is pedagogically sound.
The US context is particularly interesting. Schools are facing a lot of financial pressure, and funding has been reduced across the board. Premium schools that depend on international enrolments are also facing pressure because international enrolments have declined given the visa situation.
At the same time, everyone is grappling with AI and trying to find meaningful ways to leverage it. For us, retention is by far the number-one outcome. Elite institutions may have less of a problem, but as you go further from the elite institutions, the challenge becomes more pronounced.
Imagine a community college offering online programmes. Many of those learners are working professionals. For them, if a two-year programme becomes three years, or three years becomes four years, it may eventually result in a dropout.
Our objective is to help both the learner and the institution become more successful. The other piece is making learning more experiential and personalised. If learners have a better experience, we believe that creates stickiness and helps them get through the programme.
You have three products within LYCM. Can you explain what they actually do?
Heda: The suite is called LYCM, and there are three products– Engage, Achieve and Assist. Engage is focused on personalised, curriculum-grounded coaching. It has an AI tutor, an AI mentor and capabilities designed to remove friction for learners.
There are a lot of AI tutors in the market, but we've found that creating something that actually works well is non-trivial. When we started, engagement was around 40%. Today, we have upwards of 70% engagement. We also have a 94% positive rating from learners.
We allow learners to give a thumbs-up or thumbs-down after every interaction, so we monitor that feedback continuously.
The AI mentor is slightly different. It is about understanding where the learner is in their journey and helping them get back on track. Learners go through periods where they fall behind. The mentor can help them catch up, contextualise what they're learning and personalise the experience.
Then there is the support component. If a learner has a question, we want to answer it as quickly as possible. These are working professionals with limited time. If they get stuck and have to come back later, there is a significant opportunity cost.
And Achieve?
Heda: Achieve is more about simulations and experiential learning. Today, many programmes use static case studies. A learner gets a case study, perhaps writes a five-page PowerPoint presentation and submits it.
Oftentimes, generating feedback takes time, perhaps multiple weeks. Currently, there is no way of knowing whether the learners actually went back and looked at that feedback.
We are trying to flip the narrative entirely. In our case, the learner works with AI in real-time. They can create their own scenario or choose from scenarios we provide. Irrespective of what they choose, they get immediate feedback.
We also connect the exercise to the course curriculum. Let's say you're applying a marketing topic that has five modules. You may have covered two, but not the other three. The system can tell you that and ask you to take another shot.
We've seen learners come back and do the same exercise three or four times. That's interesting to us because learners often treat exercises as a chore. When they come back and voluntarily repeat the exercise, I think that's a good validation that the product is appealing.
There is also a benefit for institutions. Case studies are often among the most expensive things for schools to grade because you need someone senior to evaluate them. AI can make that feedback instantaneous.
 Pritam Bordoloi
And where does Assist fit in?
Heda: Assist is for operational efficiency. Grading is one area where AI can be very effective, although you have to be very careful about quality. We therefore keep grading human-in-the-loop. AI creates the first assessment, the faculty member can review it and make changes, and then they can submit the final result.
This can also allow schools to move back towards more open-ended questions. Many schools believe open-ended questions are a better way to test learners, but because of staff capacity, they sometimes revert to multiple-choice questions.
With AI tools available, they can potentially use more open-ended assessments again. Since we have the context of the entire course, we can also provide institutions with diagnostics.
We can tell them where learners are experiencing more friction, where drop-offs are happening, and whether parts of the curriculum may have become stale or outdated.
Let's get into the technology. Are you training your own model for the AI tutor?
Heda: Initially, like many enterprises, we also debated whether to create our own model or fine-tune one. We've found that the existing models work incredibly well.
Our approach is essentially retrieval-based. We take the entire curriculum and answer based on that. The technology stack is proprietary as well as open-source.
But we've spent a lot of time getting the quality right. This isn't just a case of a learner asking a question, sending it to an LLM, getting the answer and returning it.
We have a judge that evaluates the effectiveness of the response. If the score isn't strong enough, we may alter the query and try again. It's more than a single-shot interaction.
The context also matters; for instance, if you're on a course module, we can give you an answer. But if you're on a quiz page, we won't simply give you the answer. We use more of a Socratic approach and guide you through the problem rather than giving you the answer.
That raises an interesting point. If the models themselves are increasingly commoditised, where do you think the actual technology advantage sits?
Heda: I think it's in everything around the model. Everyone can say they have an AI tutor. Schools can also build their own GPT using ChatGPT. But there is a big difference between having something that works as a demonstration and having a high-quality product that can scale.
Integration is a major part of it. If a school builds a simulation separately, the learner might have to leave the LMS, go to another tool, complete the exercise and then copy the output somewhere else. It becomes clunky. The deeper integration is where the value comes in.
Can you give me an example of that integration?
Heda: When we first launched the tutor, the conventional approach was to put a chatbot icon somewhere on the page. A lot of products would put an icon or a link on the left side. So you're in a particular course module, but you have to click on the link to go into the tutor.
Now you're out of the module and into a completely different space. We created a side-by-side view. While you're watching a video or doing an exercise, the AI tutor is right next to you. References can take you to different parts of the programme rather than sending you to external sources.
But AI models still hallucinate. What happens when an AI tutor gives a student the wrong answer?
Heda: There are a few things we do. First, we ground the responses very tightly in the school's curriculum. That's critical. Moreover, faculty members may teach the subject in a particular way and follow a specific philosophy. That's why grounding the curriculum is so important.
We also have an evaluation framework that tests responses before they are served. Since we operated these tools across our own courses at scale last year, we've been able to analyse the negative feedback very thoroughly.
When there's a thumbs-down, AI initially analyses what happened, but our course leaders also review it. Interestingly, often the problem isn't hallucination. The system may not have had access to the entire set of course materials, so the answer was insufficient rather than incorrect.
 The Left Shift Bureau
How do you deal with privacy when you're working with universities across different countries?
Heda: Before we turn the product on for any school, there is a significant set of terms and conditions we go through. The first principle is learner anonymity.
We don't need to store information such as first name, last name, date of birth, Social Security number or credit card information. We completely stay away from PII.
The second thing is that our reporting cannot be correlated back to an individual learner. We can provide insights into what kinds of questions are being asked. If there is a thumbs-down interaction, we can provide the transcript so the institution has context, but it isn't tied back to a specific learner.
Data retention is another major concern. Schools want to know that once a programme is completed and the learner's access period is over, the data is purged.
These requirements have been reasonably satisfied for both Europe and the US. Schools also care about their intellectual property not being used to train LLMs. Through our enterprise agreements, we ensure that doesn't happen.
You also talk about personalisation. How much data do you actually need to personalise the experience?
Heda: Not a huge amount. We might ask the learner what industry they are in, their level within the company, their role and what they're trying to learn from the programme.
They can also describe their aspirations in their own words. That's enough to provide meaningful personalisation. For example, if I'm doing a negotiations programme and I work in healthcare, the scenarios you give me can be different from those you give someone working in construction. We can also make the reflection questions more relevant to the individual.
What about universities that decide they can build these tools themselves? Why would they need Emeritus?
Heda: It's ultimately about effort, quality and scale. We've been working on this for more than two years. Everyone can say, "I've got an AI tutor." Schools can create their own GPTs and offer them to students.
But there is a big difference between having something interesting and having something scalable. Integration with the LMS is another major factor. The real value, I think, is in creating a connected experience. That's something that takes a lot of work.
 The Left Shift Bureau
Some universities are already fine-tuning LLMs or centralising institutional data. Do you think that will become more common?
Heda: I think what you're describing is probably much rarer than the mainstream. Universities have traditionally been more inclined to leverage external products rather than build everything internally.
If you look at the education ecosystem, there are a lot of capabilities being created by vendors. Since APIs provide a framework for interoperability, the education system has actually become quite connected.
I've seen very top institutions with surprisingly light technology teams. So I would say what you're describing is more of an exception than the norm. I also have a question about the value of training an LLM specifically on university data.
The foundational models have already been trained on the world's data. I don't know how much incremental value that specific institutional data provides for education.
Where I do see value is in having good data, a good data lake and the right access controls. That doesn't necessarily mean training a model. If you have good data and the right privacy controls, you can use LLMs to query that information.
What are the biggest concerns universities raise when you pitch LYCM to them?
Heda: The concerns have changed over the years. Earlier, there was a lot more institutional resistance and legal worry. Now, institutions have gone through multiple contracts and understand better how to protect themselves, indemnify themselves, and so on.
Faculty, however, remain a concern. Some schools worry that faculty may feel AI will make them redundant. I don't think that should be the case. I see AI as a tool that allows the faculty to stretch themselves and focus on things that are more valuable. Nonetheless, the concern definitely exists.
The other issue is that schools are being approached by a lot of companies offering AI capabilities. Now, these institutions are contemplating how to choose the right tool, and how to avoid having 10 different proofs-of-concept with 10 different vendors.
Where does this ultimately go? Is LYCM essentially an AI layer on top of the LMS, or are you trying to change the underlying education model?
Heda: Today, it's more of a layer on top of the LMS. But we definitely want to go deeper. Underlying all of this, we have an in-house content management system.
If we want to move towards a more adaptive future, we need control over the content and the ability to adapt it dynamically. We spend a lot of time baking things internally, testing them on our own programmes and then taking them externally.
It's essentially a three-step process. The longer-term goal is to make education much more skills-based, personalised and adaptive. Today, education is relatively static. You have a fixed number of courses and electives. Within an elective, whether you're a strong student, a weak student, or whether you have significant background knowledge or none, you generally do the same thing.
The holy grail is having a granular view of the learner's skills and tailoring the content based on those skills. However, it's easier said than done. It has implications for how courses are built. It has implications for how they are delivered, and also for compliance because schools have to maintain accreditation and demonstrate that they continue to meet state and federal requirements.
 The Left Shift Bureau
 Pritam Bordoloi
 Pritam Bordoloi
 The Left Shift Bureau